The request clock
Long inputs and long outputs add work in different phases. One clock does not distinguish them.
Links containing ?t= open the video at a specific second.
The ideas to retain
The request changes shape after prefill
Consider a request with Lin input tokens and Lout generated tokens.
TTFT is a client-visible boundary, not one operation
A production path to first output can be decomposed as:
For reasoning models, distinguish TTFT from TTFO
The meaning of “first token” can itself change with model behavior. In current AIPerf, TTFT ends at the first token of any type, including a reasoning token, while TTFO, time to first…
Jump directly to a section
Read the reviewed transcript
This video has no narration. This transcript reproduces its on-screen text; it does not invent a spoken track.
Read, then generate
Prefill processes the prompt and builds reusable attention state.
Decode adds a token using that state without recomputing the entire history from scratch.
Long inputs and long outputs add work in different phases. One clock does not distinguish them.
The client also waits
The first token follows network transit, queuing, prefill, initial generation and delivery.
Here, removing one hundred milliseconds of queuing reduces TTFT from 450 to 350 milliseconds.
Prefill still takes two hundred. Lower TTFT does not prove a faster kernel.
Each token adds time
The first output takes 450 milliseconds. The response contains 120 tokens.
There are 119 remaining intervals, at 25 milliseconds per token in this example.
The total is 3.425 seconds. Small cadence improvements accumulate over long outputs.
An event is not a token
The client receives three tokens together every ninety milliseconds.
Events are ninety milliseconds apart; the steady cadence is equivalent to thirty per token.
Before comparing ITL or TPOT, define what each event counts and where timing begins.
Completion is not enough
Ten requests finish in ten seconds. Throughput is one request per second.
Only seven meet the latency limit fixed before the experiment.
Goodput is 0.7 per second. Counting every response hides three deadline misses.
Workload shape matters
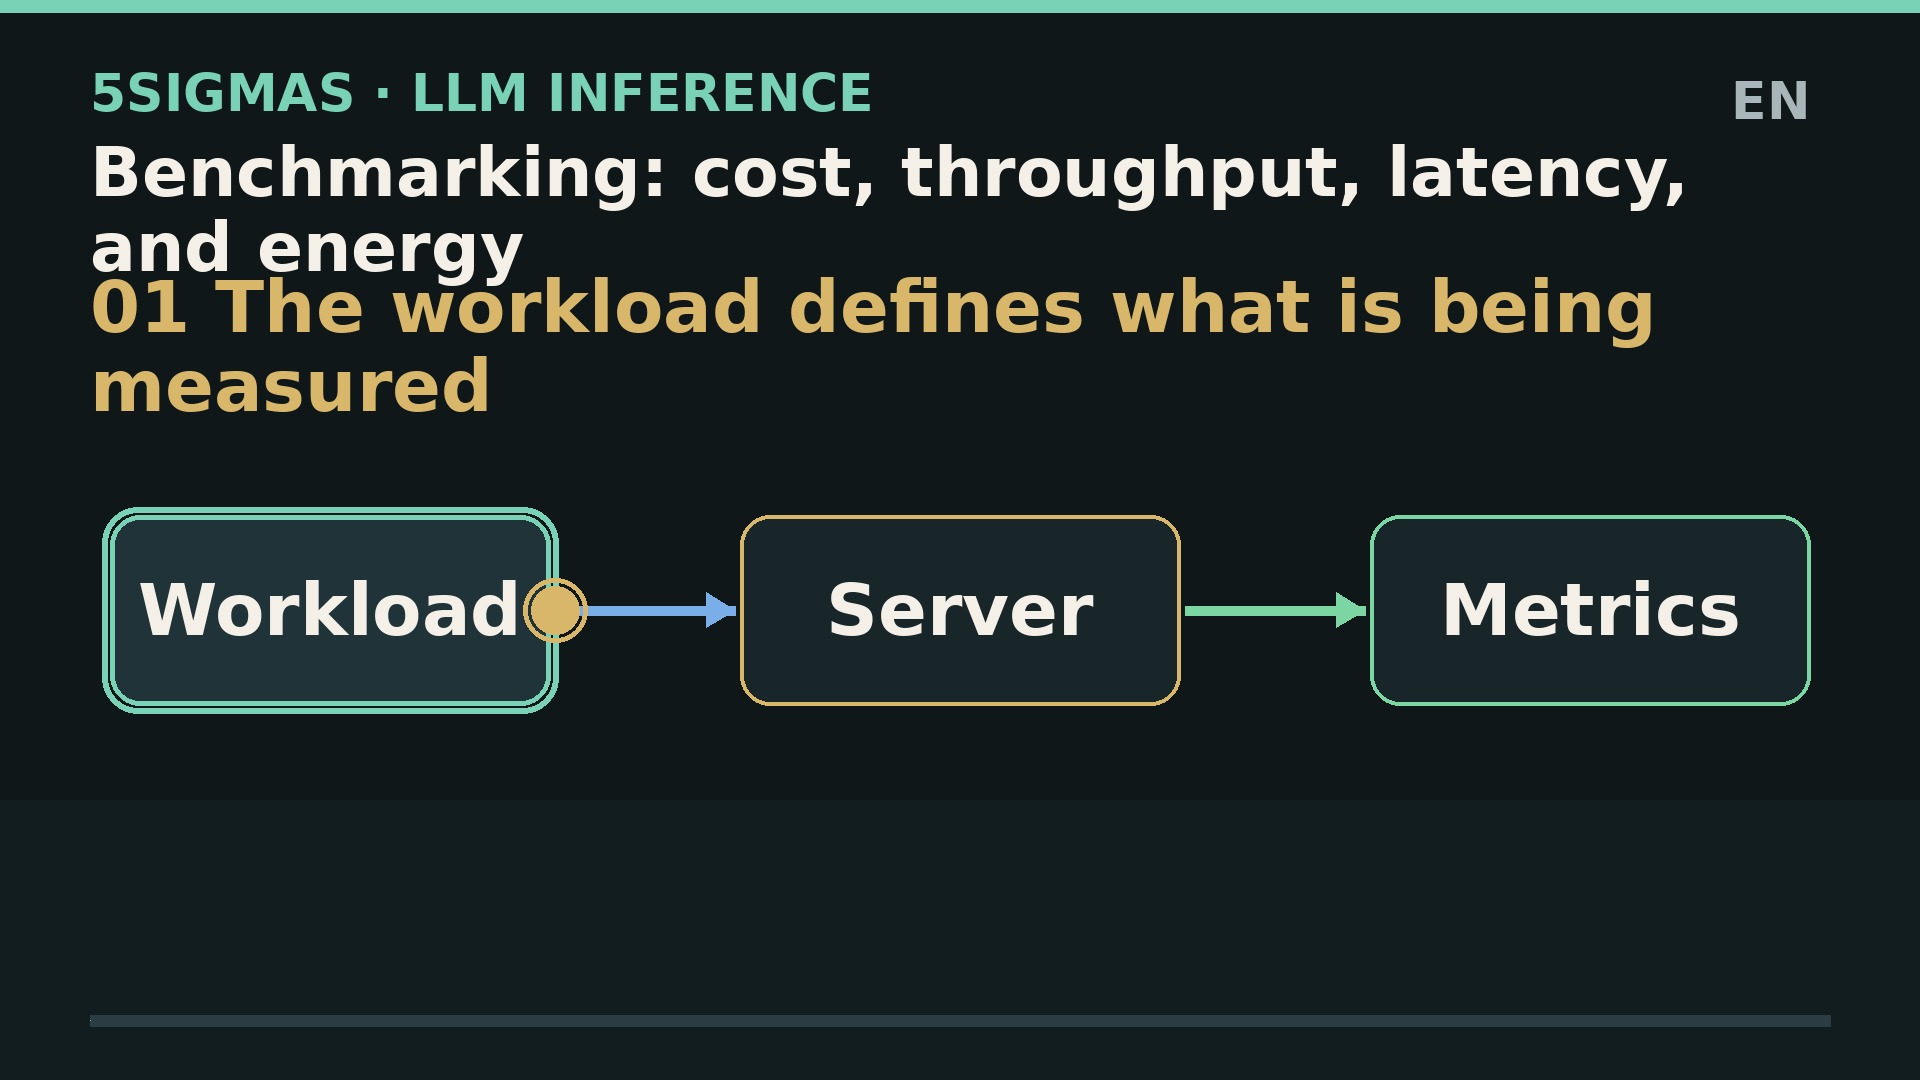
A summary can have a large input and a short output. Long-form generation reverses that balance.
Moving a case on this map changes its expected prefill and decode workload.
Compare input and output distributions, not just one global tokens-per-second figure.